From prediction to interpretation
The manuscript analyzes the Kaggle NBA Games dataset, approximately 668,000 rows, using Game Score, regression models, SHAP, and clustering. The initial target was individual on-court PLUS_MINUS.
Game Score, explainable machine learning, and six performance-based player clusters.
The manuscript analyzes the Kaggle NBA Games dataset, approximately 668,000 rows, using Game Score, regression models, SHAP, and clustering. The initial target was individual on-court PLUS_MINUS.
The draft reports a best regression R² of approximately 0.14. Instead of presenting weak prediction as a success, the work pivots toward explaining model associations and identifying six performance-based clusters.
SHAP explains fitted-model behavior; it does not establish that a statistic causes a team to win or lose. The reported numbers are manuscript results, not an independently reproduced benchmark.
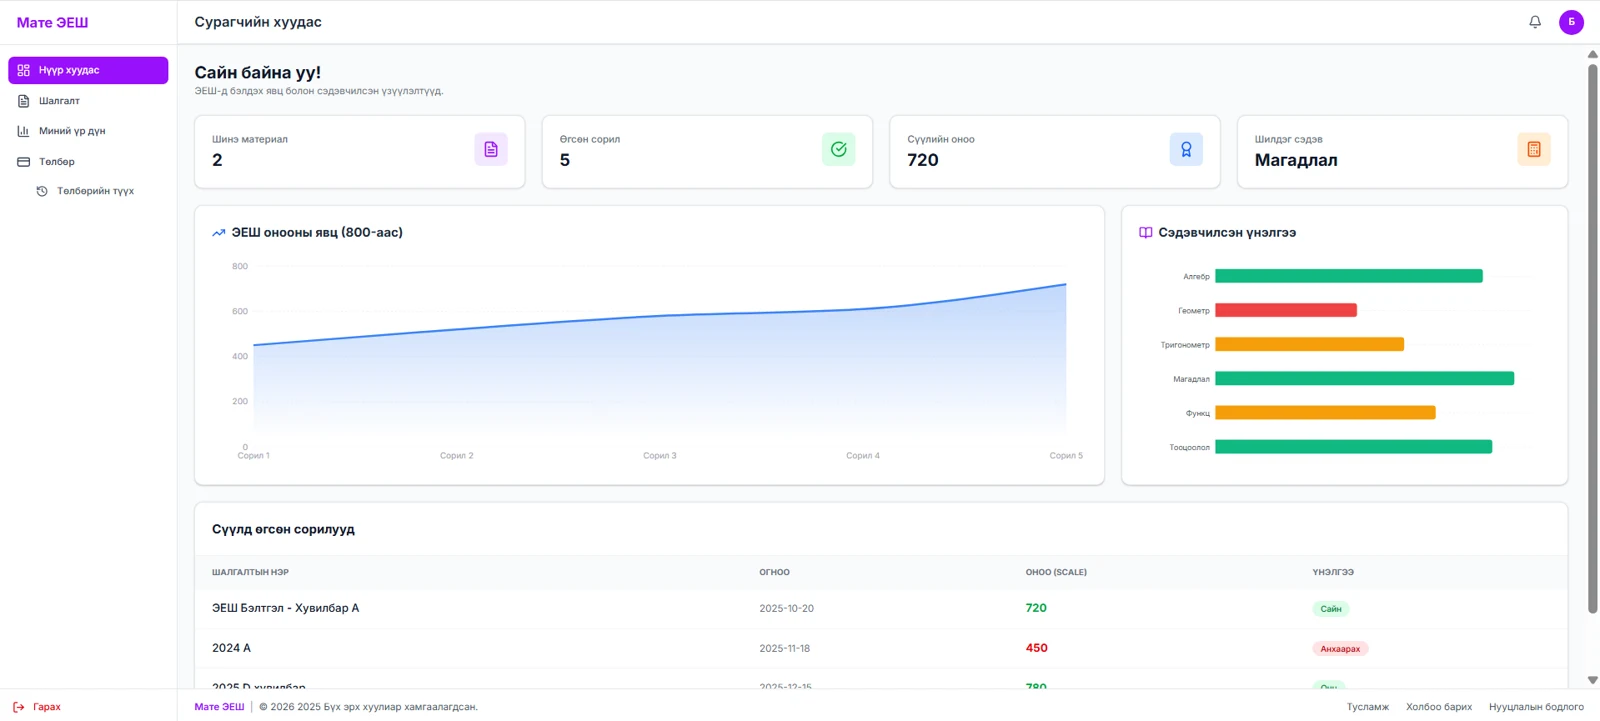 Research project
Exploring how intelligent systems can support preparation for Mongolia’s General Entrance Examination.
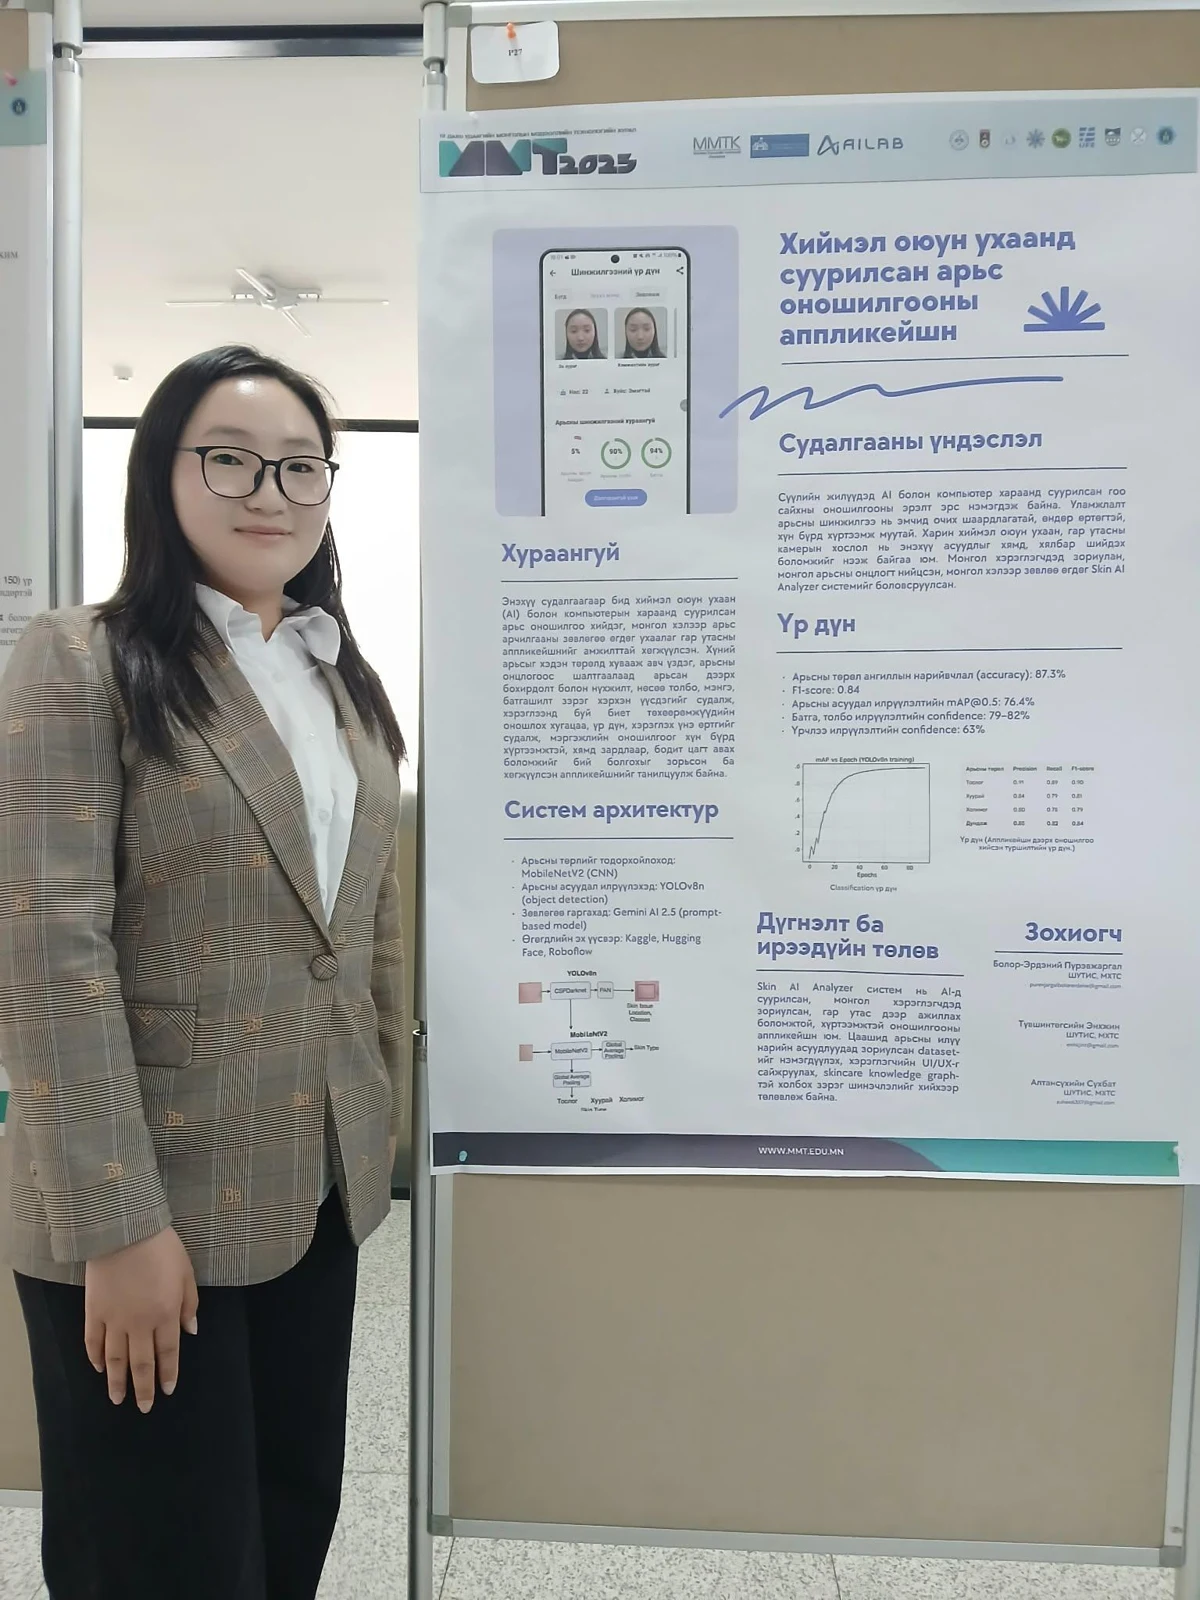 Presented · Research project
An application-oriented research project exploring AI-based skin image analysis.
Exploring connected systems for smarter waste management.
A project, a research question, a talk, or a community idea — I’d love to hear about it.